Showing posts with label TechTrends. Show all posts

Sunday, October 18, 2026

Claude vs Gemini For Google Workspace Productivity

The integration of Claude AI into Google Workspace apps like Docs, Sheets and Slides offers practical solutions for handling everyday professional tasks. According to Your AI Workflow, one standout feature is Claude’s ability to analyze past communications to draft emails, organize shared files and create detailed meeting agendas. This functionality addresses common challenges in managing collaborative workflows, offering a reliable way to streamline repetitive processes. Discover how Claude AI enhances productivity across Google Workspace with task-specific features……..Continue reading…

By:  

Source:  Geeky Gadgets

.

Critics:

Claude is a generative AI chatbot. It sometimes uses artifacts, a feature introduced in June 2024 to generate and interact with code snippets and documents. In 2025, Anthropic added a web search feature to Claude. Claude Pro and Claude Max are subscription services for additional access to Claude models. Max provides higher usage limits at an additional cost. Grouped subscriptions include Claude Team and Claude Enterprise.

According to card-spend data from Ramp, the share of businesses on its platform paying for Anthropic products rose 4.9 percentage points in February 2026, to 24.4%, the largest monthly gain Ramp had recorded for the company. Claude is reportedly named after Claude Shannon, a 20th-century mathematician who laid the foundation for information theory.

A Claude feature allows users to share chats with anyone who has the link. In September 2025, Forbes reported that hundreds of shared Claude chats had appeared in Google Search results, following similar incidents involving OpenAI’s ChatGPT and xAI’s Grok. In July 2026, shared chats and Artifacts were again found to be indexed by Google.

The BBC counted more than 200, some containing health records and corporate documents. The affected chats were those whose links had been posted on the public internet. Technical analysis suggested that a robots.txt rule blocking crawlers from shared-chat pages also prevented them from reading the noindex directive meant to keep the pages out of search results. Anthropic said the listings had been removed.

Claude is also provided through an application programming interface (API). In October 2024, the “computer use” feature was introduced by which an application can call the Claude API to attempt to give navigational control of the application via Claude’s interpretation of screen content and simulation of keyboard and mouse input.

Claude Code, released in February 2025, is an agentic command line tool to delegate coding tasks from the terminal using natural language prompts. It was made generally available in May 2025 alongside Claude 4. Based on enterprise adoption, Anthropic reported a 5.5x increase in Claude Code revenue by July.

On October 20, 2025, Anthropic launched a web version of Claude Code and a sandboxing feature. Coinciding with performance improvements tied to Claude Opus 4.5, Claude Code went viral during the 2025–2026 winter holidays when people had time to experiment with it, including many non-programmers who used it for vibe coding.

In August 2025, Anthropic reported that cybercriminals it designated “GTG-2002” had used Claude Code in a data-extortion campaign against at least 17 organizations. In November 2025, Anthropic said that in September a China-based cybercrime group had used Claude Code to automate 80–90% of its espionage cyberattacks against 30 organizations.

Claude Code is used by Microsoft and Google, and was used by OpenAI employees until August 2025, when Anthropic revoked OpenAI’s API access, calling it “a direct violation of our terms of service”. In February 2026, Anthropic introduced Claude Code Security, which reviews codebases to identify vulnerabilities. In March 2026, the source code for the Claude Code command-line interface application was leaked, revealing multiple upcoming features and models.

In May 2026, Anthropic introduced “Dreaming”, a research-preview feature of its Managed Agents API that consolidates an agent’s persistent memory between sessions by merging duplicates and removing stale entries; a memory consolidation feature called autoDream had been identified in the March source code leak.

Claude Cowork is a tool similar to Claude Code but with a graphical user interface, aimed at non-technical users. It was released in January 2026 as a “research preview”. Cowork is available as a desktop application for Mac and Windows and through a web interface. It provides Claude with access to a sandboxed shell and to user-selected folders on the local file system, allowing the model to read, write and edit files, execute code, and chain multi-step tasks within a single conversation, such as organizing files on a user’s computer or generating documents from material in a local folder.

A Wall Street Journal reporter who tested the tool noted user concerns about granting an AI agent broad access to a personal computer. An early user reported that, after asking Cowork to organize the files on the desktop of his wife’s computer, it deleted all the family photos requiring the restoration of the images from an iCloud backup.

In February 2026, Anthropic announced a wider enterprise release of Cowork, adding connectors for services such as Google Drive, Gmail, Docusign and FactSet, and customizable plugins for domains including financial analysis, engineering and human resources.

The company described the update as a transition into an “enterprise-grade product”. In March 2026, Anthropic added Dispatch, which lets users send Cowork tasks from a phone to their computer, and allows Claude to operate programs on the user’s computer, such as web browsers or spreadsheet applications, to carry out tasks. According to developers, Cowork was mostly built by Claude Code.

Claude models are generative pre-trained transformers that have been trained to predict the next word in large amounts of text. Then, they have been fine-tuned using reinforcement learning from human feedback (RLHF) and constitutional AI in an attempt to enforce ethical guidelines.ClaudeBot searches the web for content. It was criticized by iFixit in 2024 for accessing their site over a million times a day to scrape content without permission, and also for the resulting excessive load on their system.

Anthropic introduced an approach to AI alignment called “Constitutional AI”. The constitution is a document used to train Claude to be harmless and helpful without relying on extensive or expensive human feedback. Time described this constitution as “somewhere between a moral philosophy thesis and a company culture blog post”.

Friday, October 16, 2026

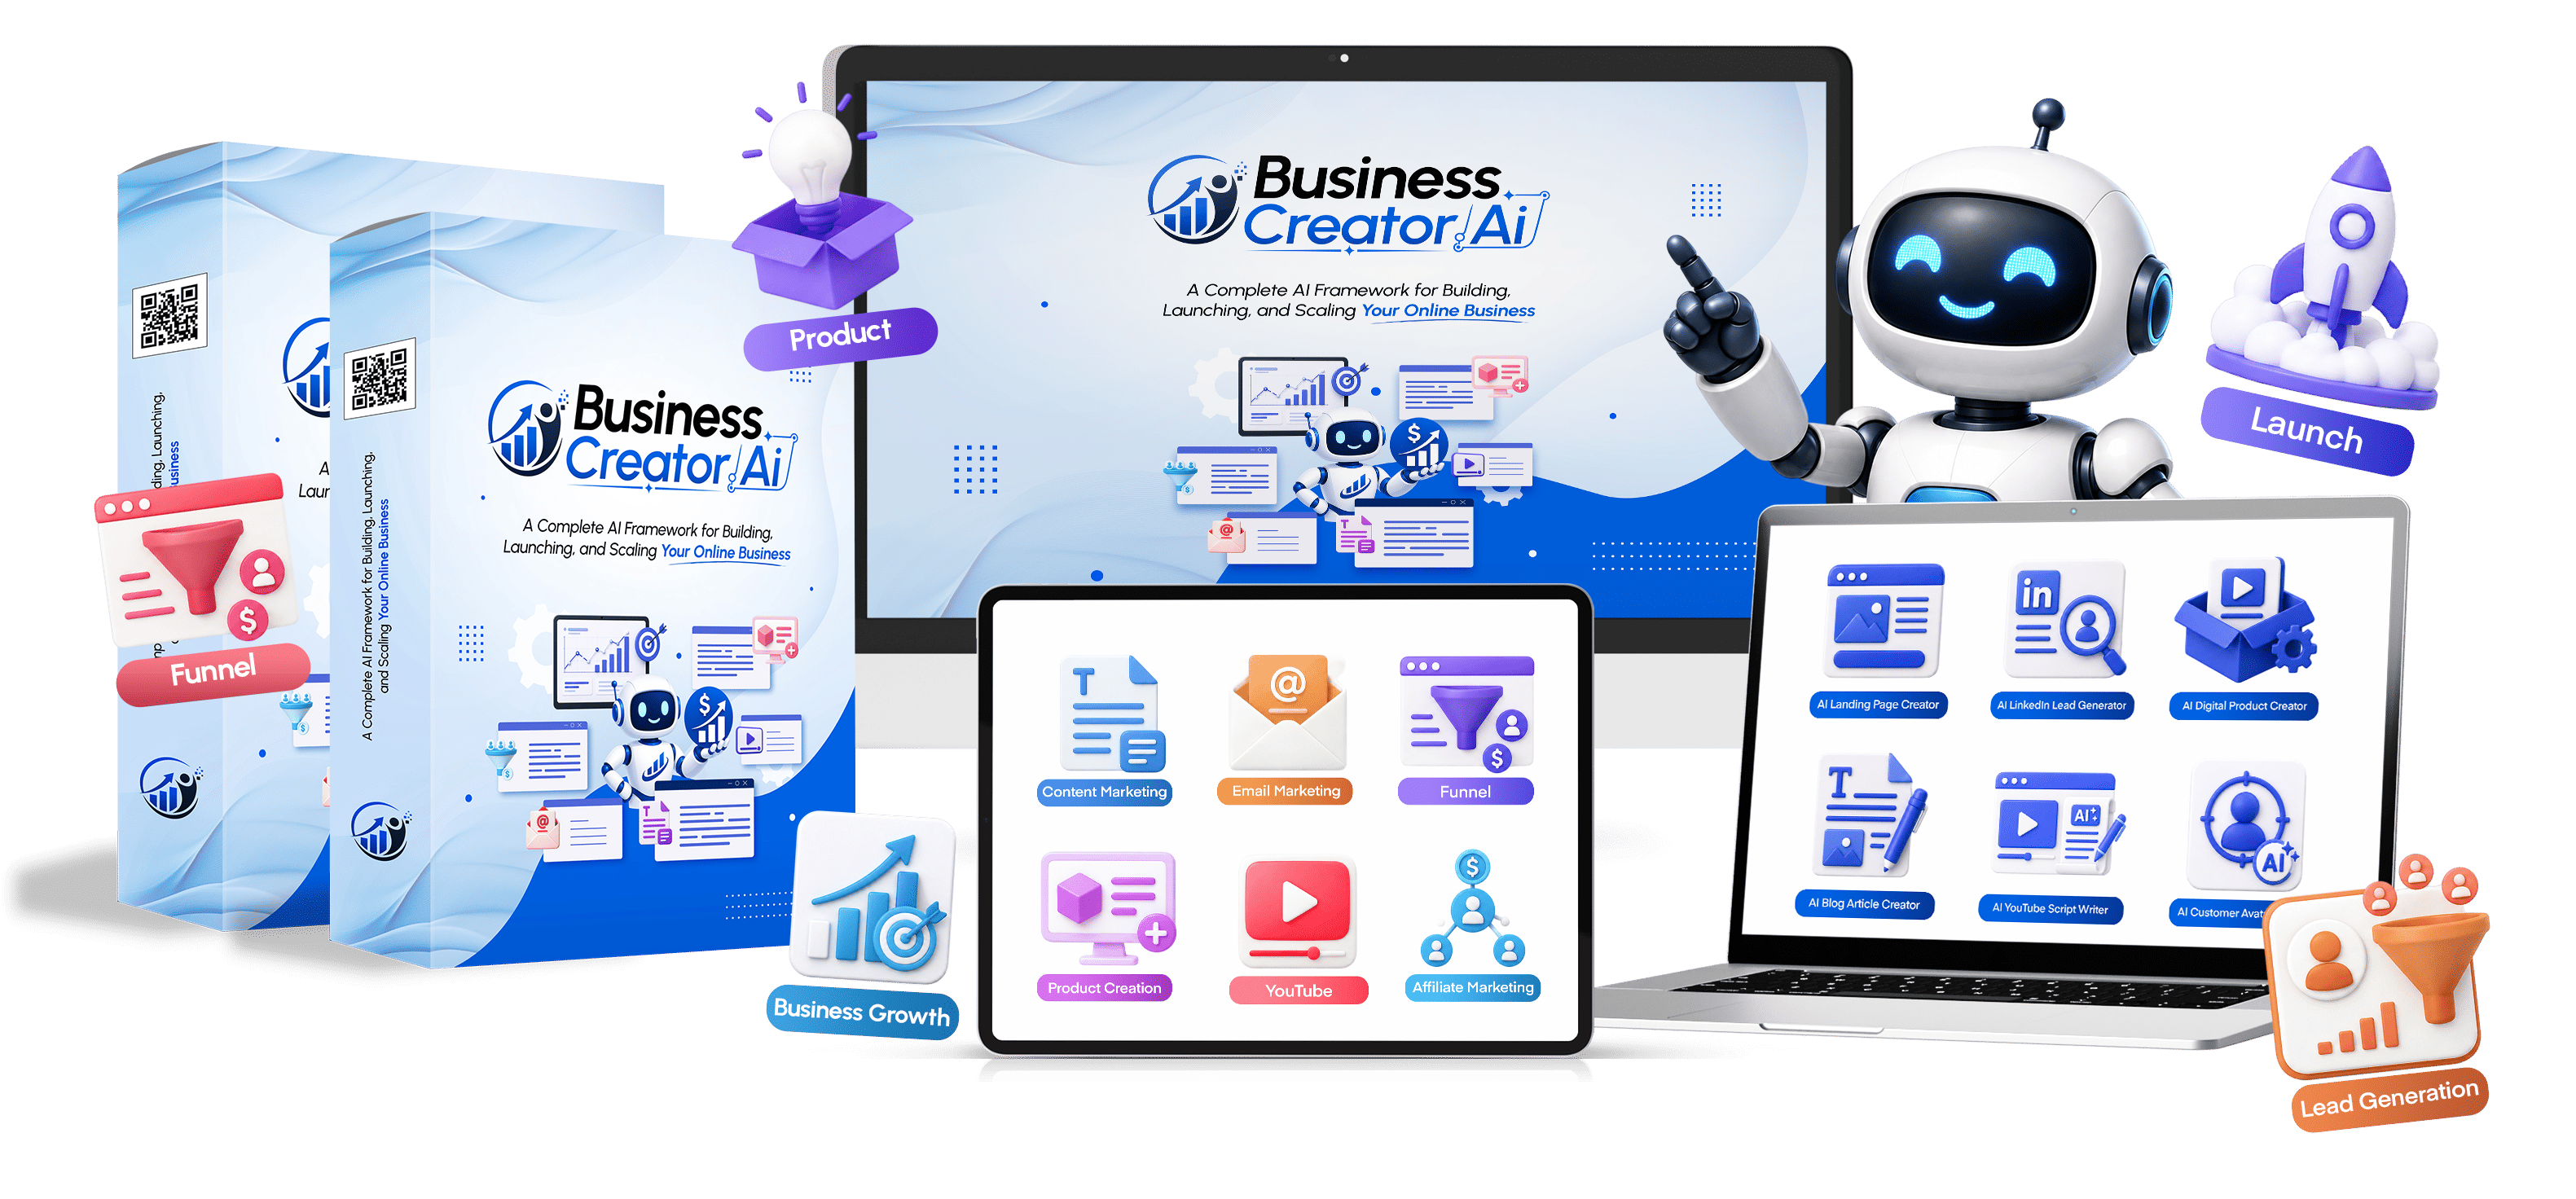
Business Creator AI™ With PLR The 15 Essential AI Business GPTs

Business Creator AI™ with PLR gives you everything you need to create digital products, generate leads, build high-converting funnels, write persuasive marketing content, attract customers, and launch your online business faster using the power of AI. Instead of spending weeks trying to figure out what to create, who to sell to, or how to launch, you simply follow proven AI-powered prompts that guide you through the entire process—step by step.

In just a few hours, you could create a growth able digital product, define your ideal customer, build a compelling lead magnet, write a high-converting landing page, generate persuasive email campaigns, produce engaging blog articles, create YouTube scripts, craft affiliate review content, and map out a complete product launch strategy. No staring at a blank screen. No endless brainstorming.

  • Generate and develop digital product ideas
  • Understand your ideal customers and their needs.
  • Create lead generation strategies and prospecting content.
  • Build landing pages and improve conversion-focused messaging.
  • Create email sequences and promotional campaigns.
  • Produce blog content, hooks, and YouTube scripts.
  • Create affiliate review and promotional content.
  • Organize and plan your product launches.

No expensive agencies or freelancers. Just a faster, smarter way to turn ideas into real digital products and complete business assets. Giving you the AI-powered framework to create, customize, publish, and launch your next online business with confidence and speed. We started exactly where you are now-unsure what to create, who to sell to, or how to launch. So we built a system of AI GPTs and used it to launch our own digital products.

You don’t need years of experience. You don’t need a big team. You don’t need to spend months figuring out “what works.” You just need the same system we used-and the willingness to follow it-so you can start earning too. Every GPT, every workflow, every step that helped us go from idea to income is now packed inside Business Creator AI™. No guesswork. No trial and error. No wasted weeks staring at a blank screen wondering where to start.

15+ Specialized GPTs Working Together to Help You Find Customers, Create Products, Build Funnels, Generate Content & Grow Your Online Business. And visually show the 9 departments surrounding a central Business Creator AI™ hub.

Source: Business GPTs

.

AIBusiness ,GPTs ,ArtificialIntelligence ,BusinessInnovation ,TechTrends ,FutureOfWork ,DigitalTransformation ,AIRevolution ,SmartTechnology ,Entrepreneurship ,BusinessGrowth ,AIApplications ,GPTTechnology ,AIContentCreation ,MachineLearning ,Innovation ,BusinessProductivity ,DataDriven ,AIOnSocialMedia

Thursday, October 15, 2026

What’s The Difference Between Machine Learning and Deep Learning?

Login (Shutterstock)

Artificial intelligence is everywhere these days, but the fundamentals of how this influential new technology works can be confusing. Two of the most important fields in AI development are “machine learning” and its sub-field, “deep learning.” Here’s a quick explanation of what these two important disciplines are, and how they’re contributing to the evolution of automation. It’s worth reminding ourselves what AI actually is. Proponents of artificial intelligence say they hope to someday create a machine that can “think” for itself.……..Story continues…

By: Lucas Ropek / Gizmodo

Source: Quartz

.

Critics:

A machine learning model is a type of mathematical model that, after being “trained” on a given dataset, can be used to make predictions or classifications on new data. During training, a learning algorithm iteratively adjusts the model’s internal parameters to minimize errors in its predictions.

By extension, the term “model” can refer to several levels of specificity, from a general class of models and their associated learning algorithms to a fully trained model with all its internal parameters tuned. Various types of models have been used and researched for machine learning systems, picking the best model for a task is called model selection.

As a scientific endeavor, machine learning grew out of the quest for artificial intelligence (AI). In the early days of AI as an academic discipline, some researchers were interested in having machines learn from data. They attempted to approach the problem with various symbolic methods, as well as what were then termed “neural networks”; these were mostly perceptrons and other models that were later found to be reinventions of the generalized linear models of statistics. 

Probabilistic reasoning was also employed, especially in automated medical diagnosis. However, an increasing emphasis on the logical, knowledge-based approach caused a rift between AI and machine learning. Probabilistic systems were plagued by theoretical and practical problems of data acquisition and representation.  By 1980, expert systems had come to dominate AI, and statistics was out of favor.

Work on symbolic/knowledge-based learning did continue within AI, leading to inductive logic programming(ILP), but the more statistical line of research was now outside the field of AI proper, in pattern recognition and information retrieval.  Neural networks research had been abandoned by AI and computer science around the same time. This line, too, was continued outside the AI/CS field, as “connectionism”, by researchers from other disciplines including John Hopfield, David Rumelhart, and Geoffrey Hinton. Their main success came in the mid-1980s with the reinvention of backpropagation.

Machine learning (ML), reorganized and recognized as its own field, started to flourish in the 1990s. The field changed its goal from achieving artificial intelligence to tackling solvable problems of a practical nature. It shifted focus away from the symbolic approaches it had inherited from AI, and toward methods and models borrowed from statistics, fuzzy logic, and probability theory. This section is an excerpt from Data compression Machine learning.

There is a close connection between machine learning and compression. A system that predicts the posterior probabilities of a sequence given its entire history can be used for optimal data compression (by using arithmetic coding on the output distribution). Conversely, an optimal compressor can be used for prediction (by finding the symbol that compresses best, given the previous history). This equivalence has been used as a justification for using data compression as a benchmark for “general intelligence”.

An alternative view can show compression algorithms implicitly map strings into implicit feature space vectors, and compression-based similarity measures compute similarity within these feature spaces. For each compressor C(.) we define an associated vector space ℵ, such that C(.) maps an input string x, corresponding to the vector norm ||~x||. An exhaustive examination of the feature spaces underlying all compression algorithms is precluded by space; instead, feature vectors chooses to examine three representative lossless compression methods, LZW, LZ77, and PPM.

According to AIXI theory, a connection more directly explained in Hutter Prize, the best possible compression of x is the smallest possible software that generates x. For example, in that model, a zip file’s compressed size includes both the zip file and the unzipping software, since you can not unzip it without both, but there may be an even smaller combined form.

Examples of AI-powered audio/video compression software include NVIDIA Maxine, AIVC. Examples of software that can perform AI-powered image compression include OpenCV, TensorFlow, MATLAB’s Image Processing Toolbox (IPT) and High-Fidelity Generative Image Compression. In unsupervised machine learning, k-means clustering can be utilized to compress data by grouping similar data points into clusters.

This technique simplifies handling extensive datasets that lack predefined labels and finds widespread use in fields such as image compression. Data compression aims to reduce the size of data files, enhancing storage efficiency and speeding up data transmission. K-means clustering, an unsupervised machine learning algorithm, is employed to partition a dataset into a specified number of clusters, k, each represented by the centroid of its points.

This process condenses extensive datasets into a more compact set of representative points. Particularly beneficial in image and signal processing, k-means clustering aids in data reduction by replacing groups of data points with their centroids, thereby preserving the core information of the original data while significantly decreasing the required storage space.

Large language models (LLMs) are also capable of lossless data compression, as demonstrated by DeepMind’s research with the Chinchilla 70B model. Developed by DeepMind, Chinchilla 70B effectively compressed data, outperforming conventional methods such as Portable Network Graphics (PNG) for images and Free Lossless Audio Codec (FLAC) for audio.

It achieved compression of image and audio data to 43.4% and 16.4% of their original sizes, respectively. Machine learning and data mining often employ the same methods and overlap significantly, but while machine learning focuses on prediction, based on known properties learned from the training data, data mining focuses on the discovery of (previously) unknown properties in the data (this is the analysis step of knowledge discovery in databases).

Data mining uses many machine learning methods, but with different goals; on the other hand, machine learning also employs data mining methods as “unsupervised learning” or as a preprocessing step to improve learner accuracy. Much of the confusion between these two research communities (which do often have separate conferences and separate journals, ECML PKDD being a major exception) comes from the basic assumptions they work with:

In machine learning, performance is usually evaluated with respect to the ability to reproduce known knowledge, while in knowledge discovery and data mining (KDD) the key task is the discovery of previously unknown knowledge. Evaluated with respect to known knowledge, an uninformed (unsupervised) method will easily be outperformed by other supervised methods, while in a typical KDD task, supervised methods cannot be used due to the unavailability of training data.

Machine learning also has intimate ties to optimization: Many learning problems are formulated as minimization of some loss function on a training set of examples. Loss functions express the discrepancy between the predictions of the model being trained and the actual problem instances (for example, in classification, one wants to assign a label to instances, and models are trained to correctly predict the preassigned labels of a set of examples).

Characterizing the generalization of various learning algorithms is an active topic of current research, especially for deep learning algorithms. Machine learning and statistics are closely related fields in terms of methods, but distinct in their principal goal: statistics draws population inferences from a sample, while machine learning finds generalizable predictive patterns. 

According to Michael I. Jordan, the ideas of machine learning, from methodological principles to theoretical tools, have had a long pre-history in statistics. He also suggested the term data science as a placeholder to call the overall field. Conventional statistical analyses require the a priori selection of a model most suitable for the study data set. In addition, only significant or theoretically relevant variables based on previous experience are included for analysis.

In contrast, machine learning is not built on a pre-structured model; rather, the data shape the model by detecting underlying patterns. The more variables (input) used to train the model, the more accurate the ultimate model will be. Leo Breiman distinguished two statistical modeling paradigms: data model and algorithmic model, wherein “algorithmic model” means more or less the machine learning algorithms like Random Forest.

Some statisticians have adopted methods from machine learning, leading to a combined field that they call statistical learning. Analytical and computational techniques derived from deep-rooted physics of disordered systems can be extended to large-scale problems, including machine learning, e.g., to analyze the weight space of deep neural networks. Statistical physics is thus finding applications in the area of medical diagnostics.

Machine learning approaches are traditionally divided into three broad categories, which correspond to learning paradigms, depending on the nature of the “signal” or “feedback” available to the learning system:

  • Supervised learning: The computer is presented with example inputs and their desired outputs, given by a “teacher”, and the goal is to learn a general rule that maps inputs to outputs.
  • Unsupervised learning: No labels are given to the learning algorithm, leaving it on its own to find structure in its input. Unsupervised learning can be a goal in itself (discovering hidden patterns in data) or a means towards an end (feature learning).
  • Reinforcement learning: A computer program interacts with a dynamic environment in which it must perform a certain goal (such as driving a vehicle or playing a game against an opponent). As it navigates its problem space, the program is provided feedback that’s analogous to rewards, which it tries to maximize.

Although each algorithm has advantages and limitations, no single algorithm works for all problems.

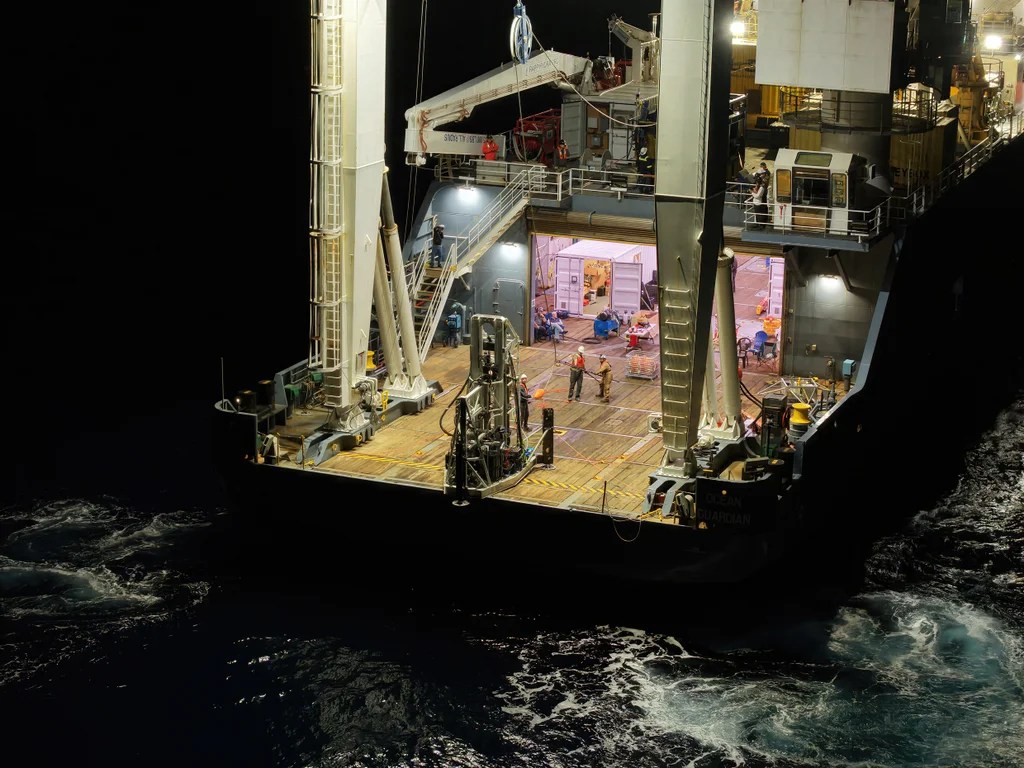
This Startup Just Tested Turning An Underwater Volcano Into a Power Plant

Photo: Endurance Energy In theory, if it works, it could be a large power resource. Around the Pacific’s Ring of Fire, Redd says that there ...